Reinforcement Learning e
a Era da Experiência
Instituto de Informática
Universidade Federal do Rio Grande do Sul (UFRGS)
Sobre Mim
- Professor do Instituto de Informática – UFRGS
- Departamento de Informática Teórica
- Pesquisa em Inteligência Artificial
- Aprendizado por Reforço
- Transferência de Conhecimento
- Robótica
- Doutorado em Computação – UFRGS (2025)
- Período Sanduíche no AI Lab – VUB (Bélgica)
- Estágio de pesquisa na Disney Research Zürich
Alan Turing e IA
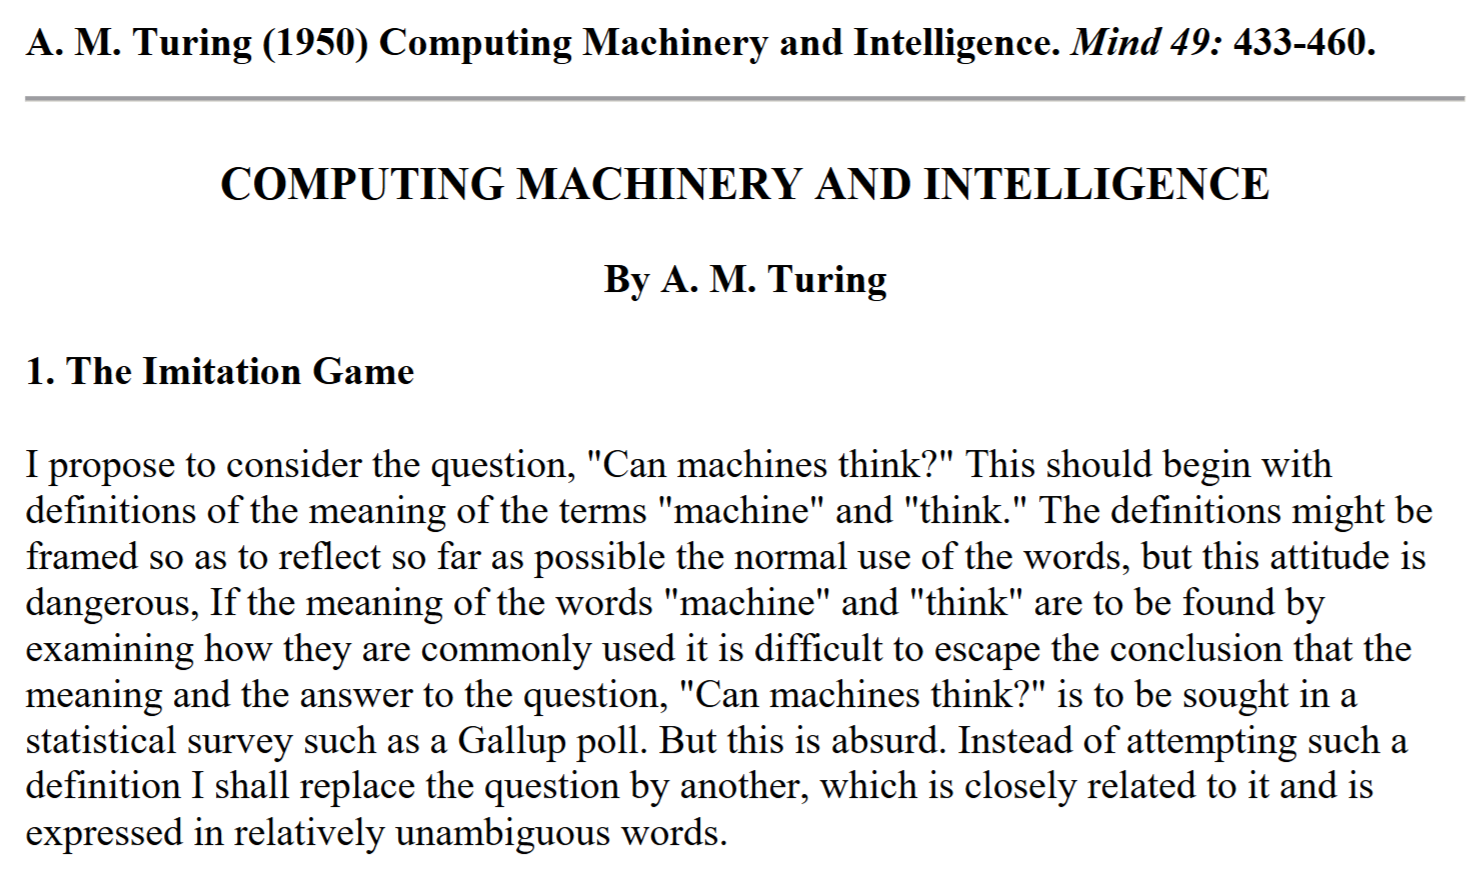
“Máquinas conseguem pensar?”
“Um computador mereceria ser chamado de inteligente se pudesse enganar um humano a acreditar que também é humano.”
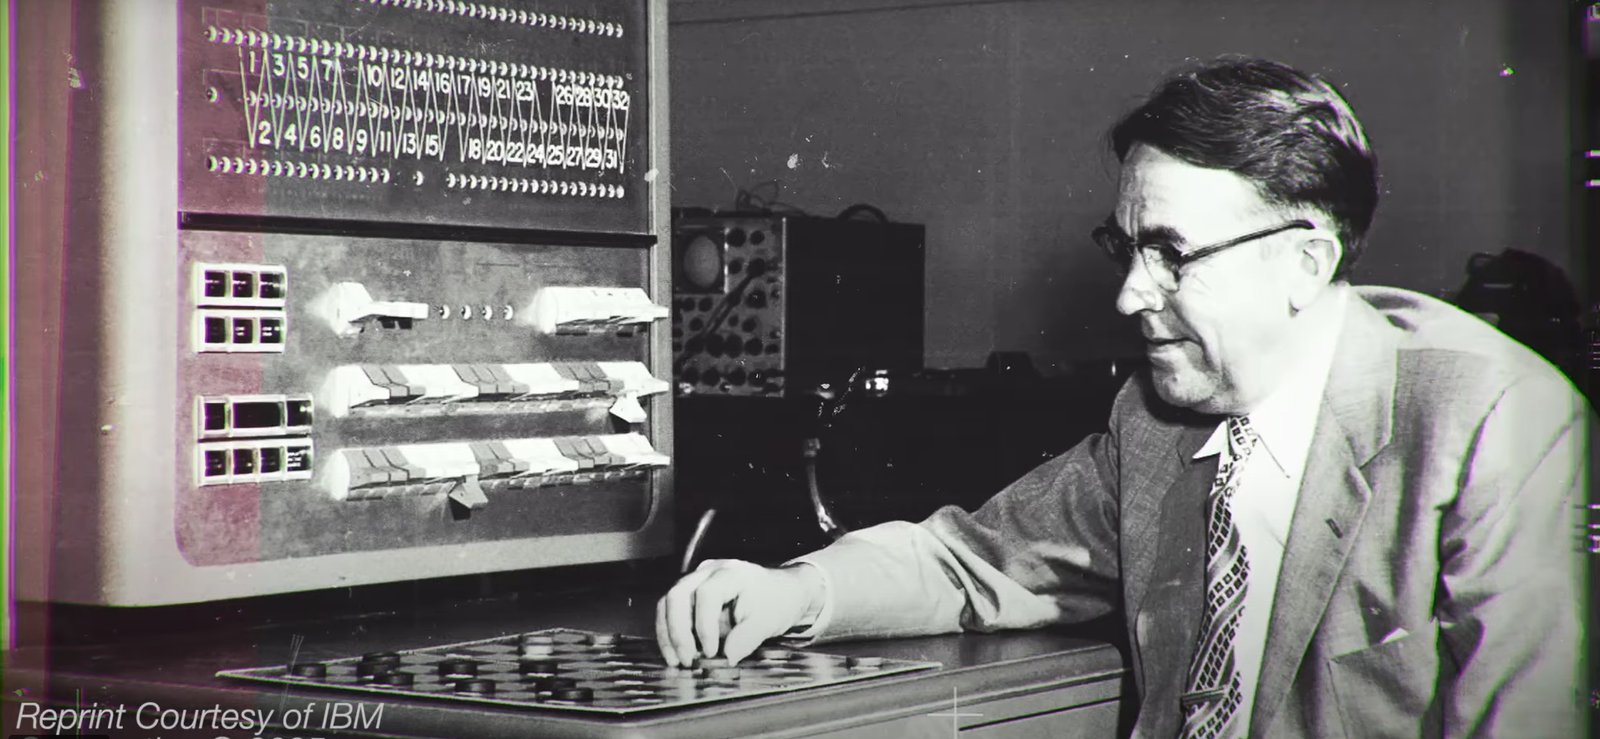
Arthur Samuel – Checkers (1959)
- Popularizou o termo “machine learning”.
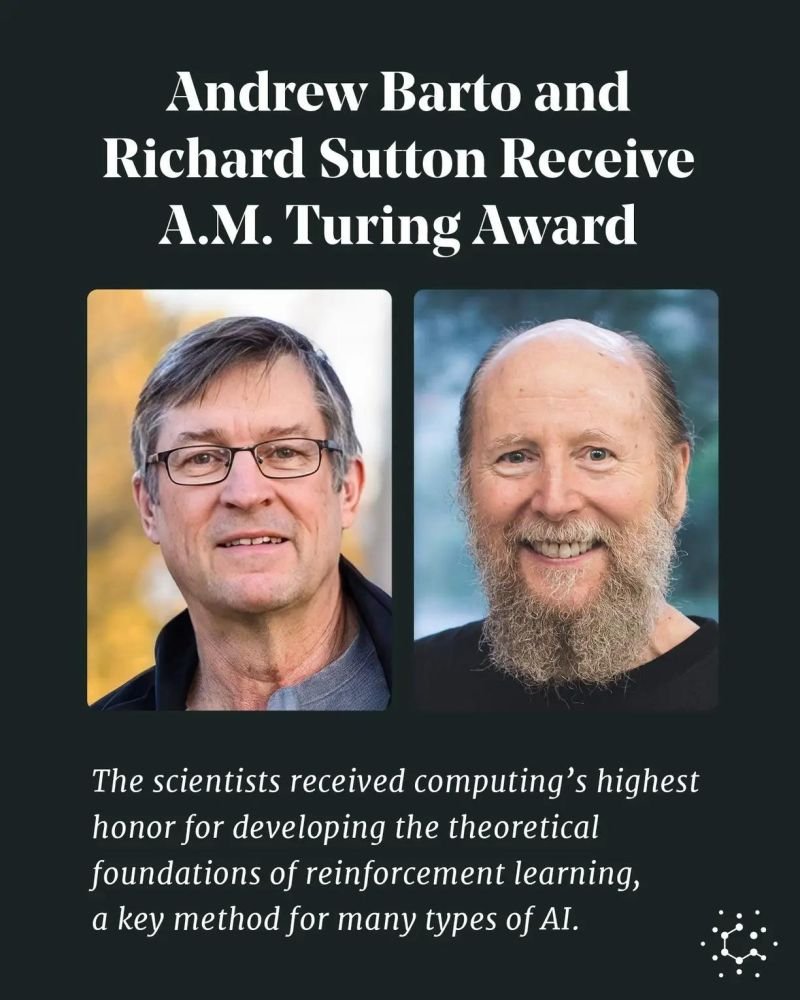
Turing Award 2025
- Andrew Barto e Richard Sutton
- Prêmio mais importante na computação
- “Desenvolvimento das fundações teóricas de reinforcement learning, um método chave em muitos tipos de IA.”
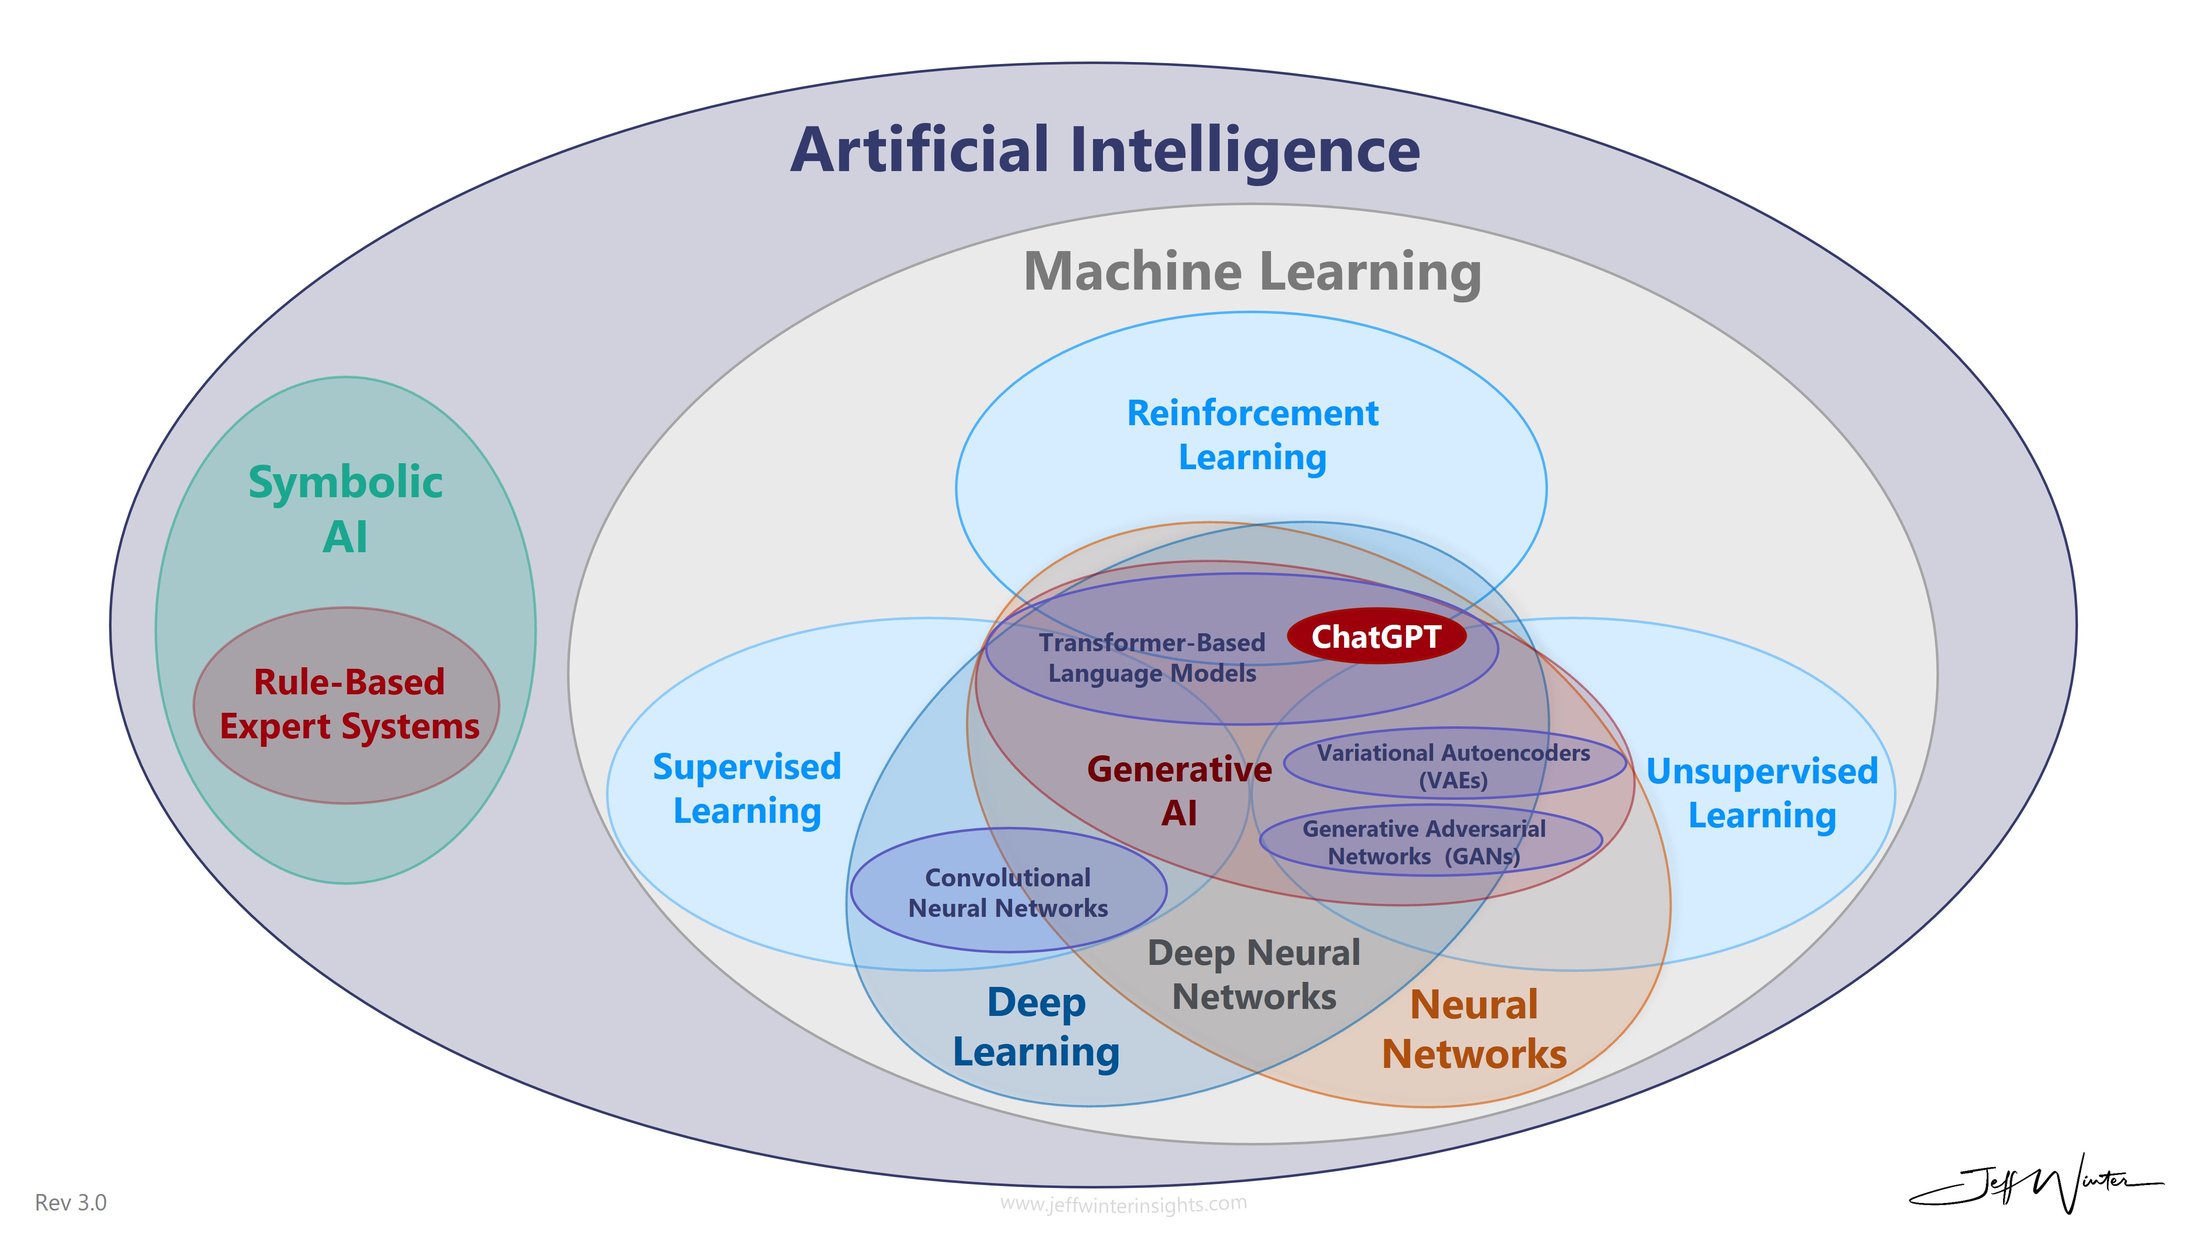
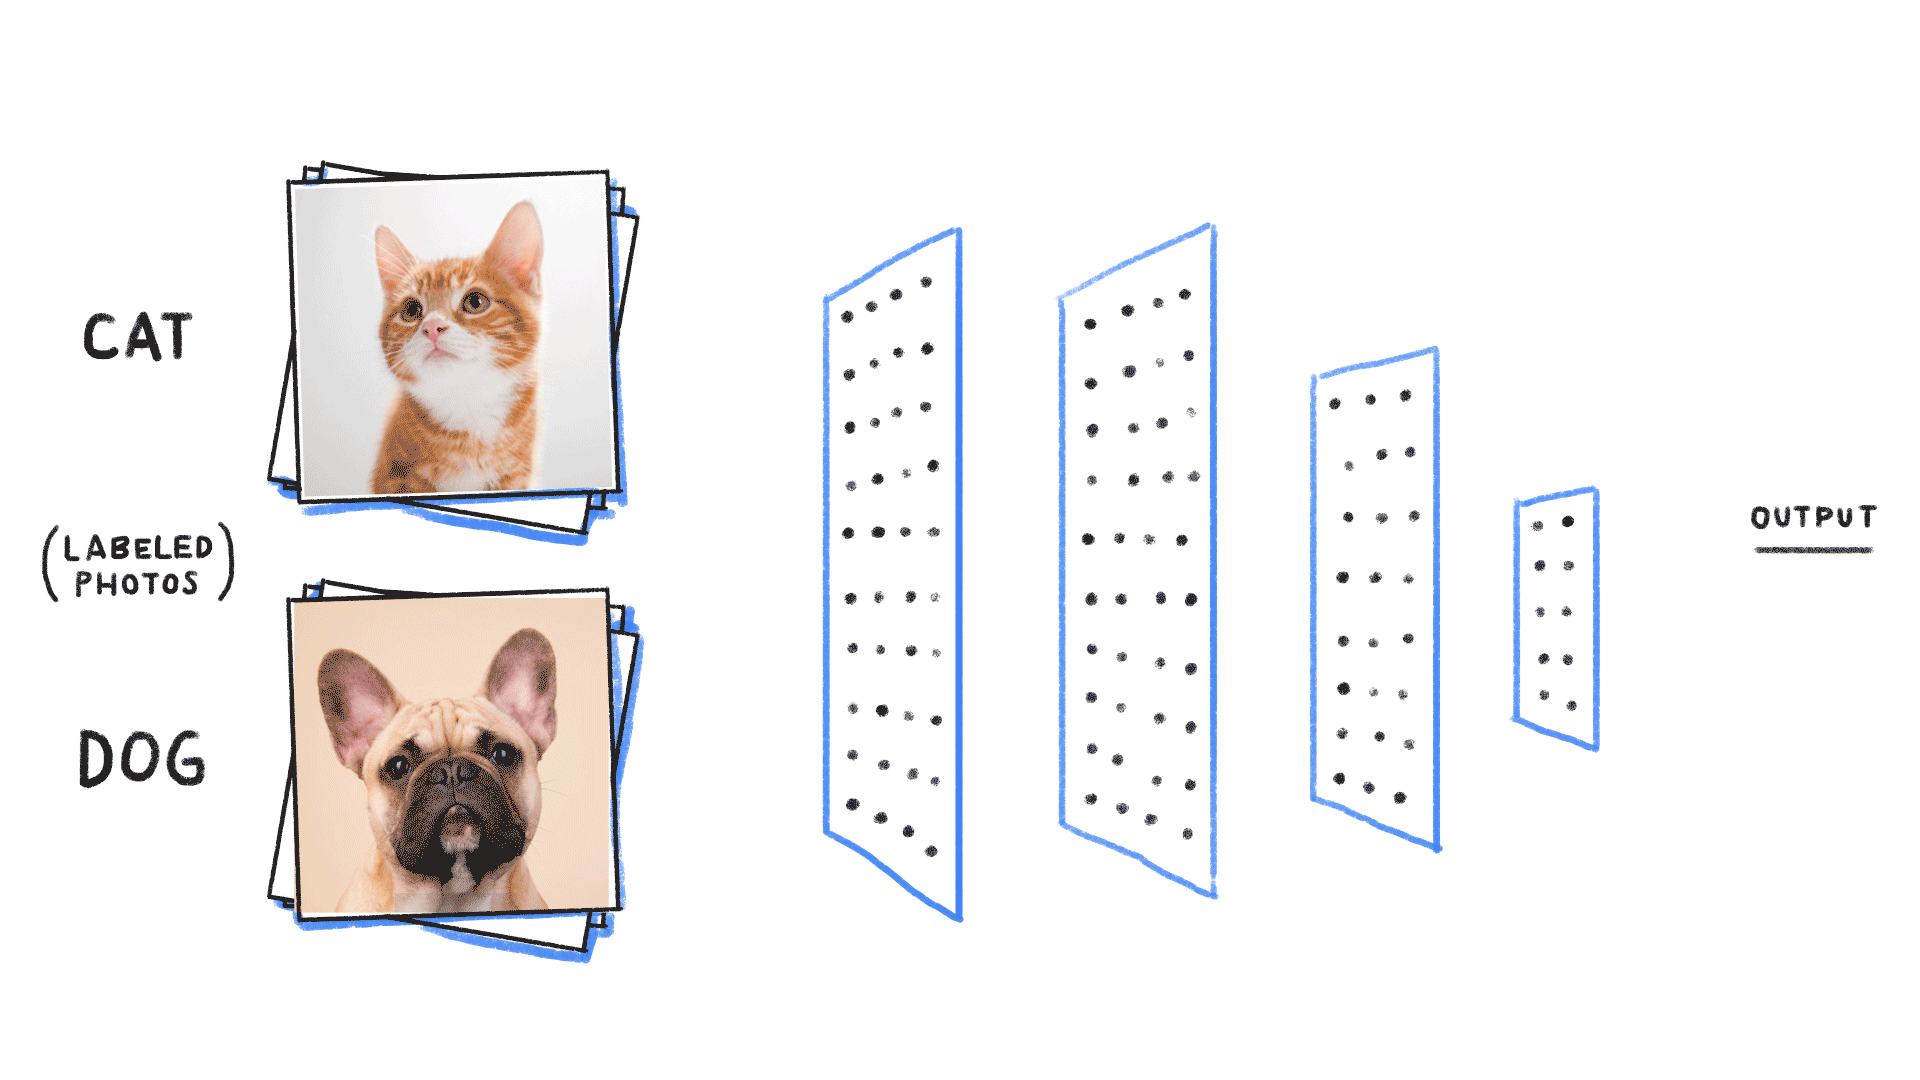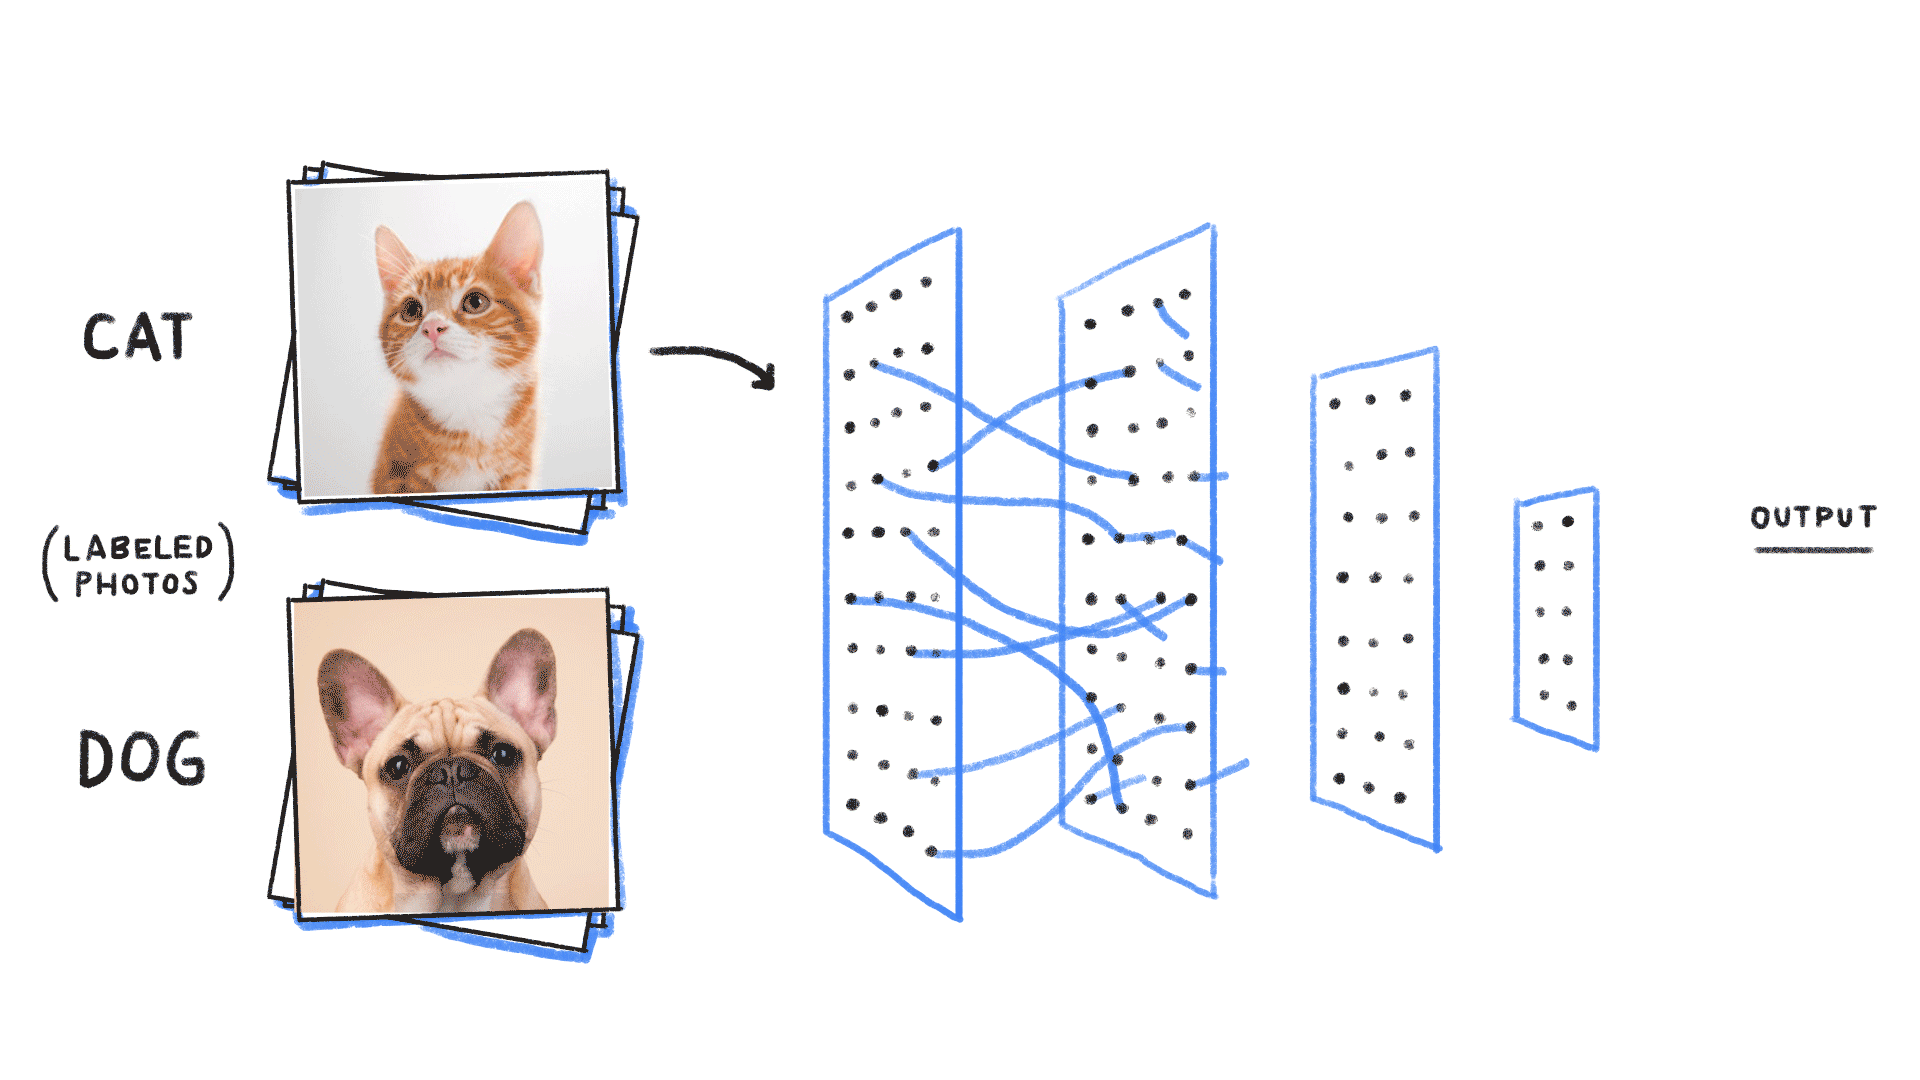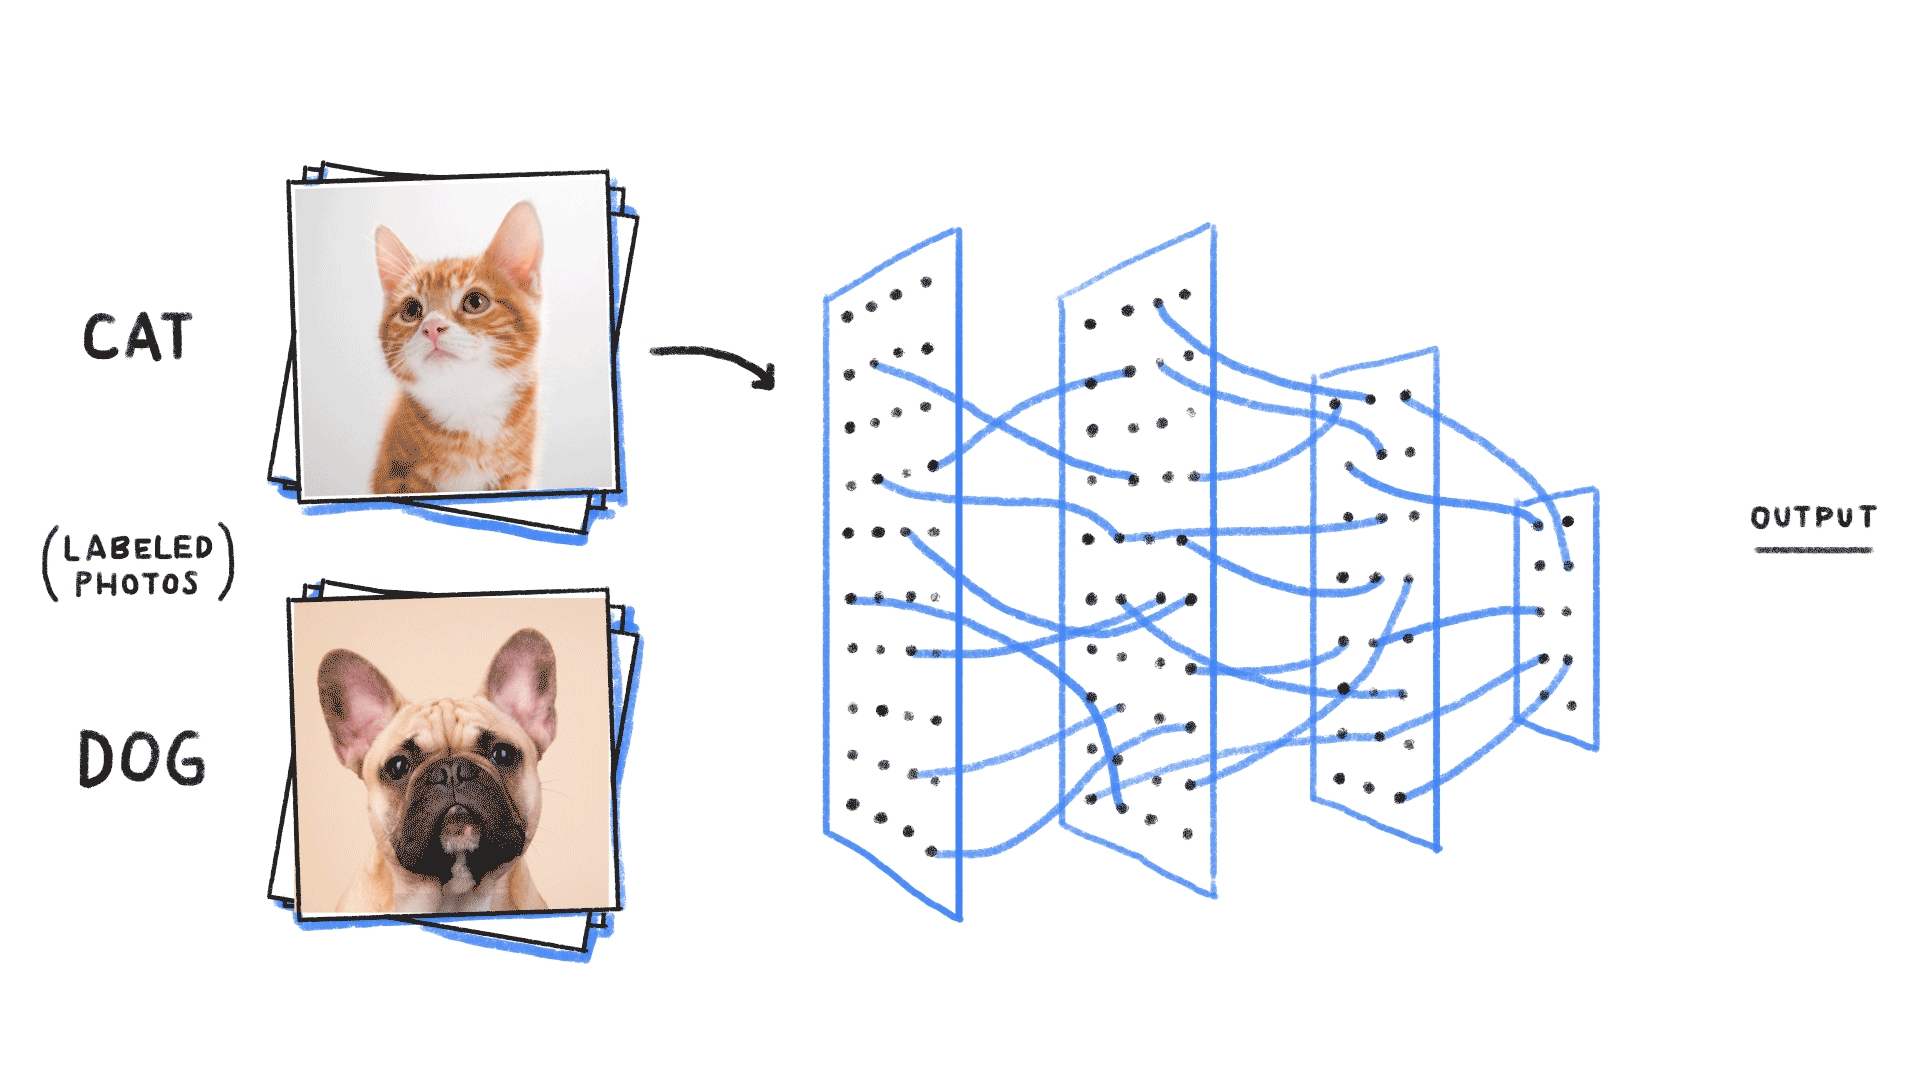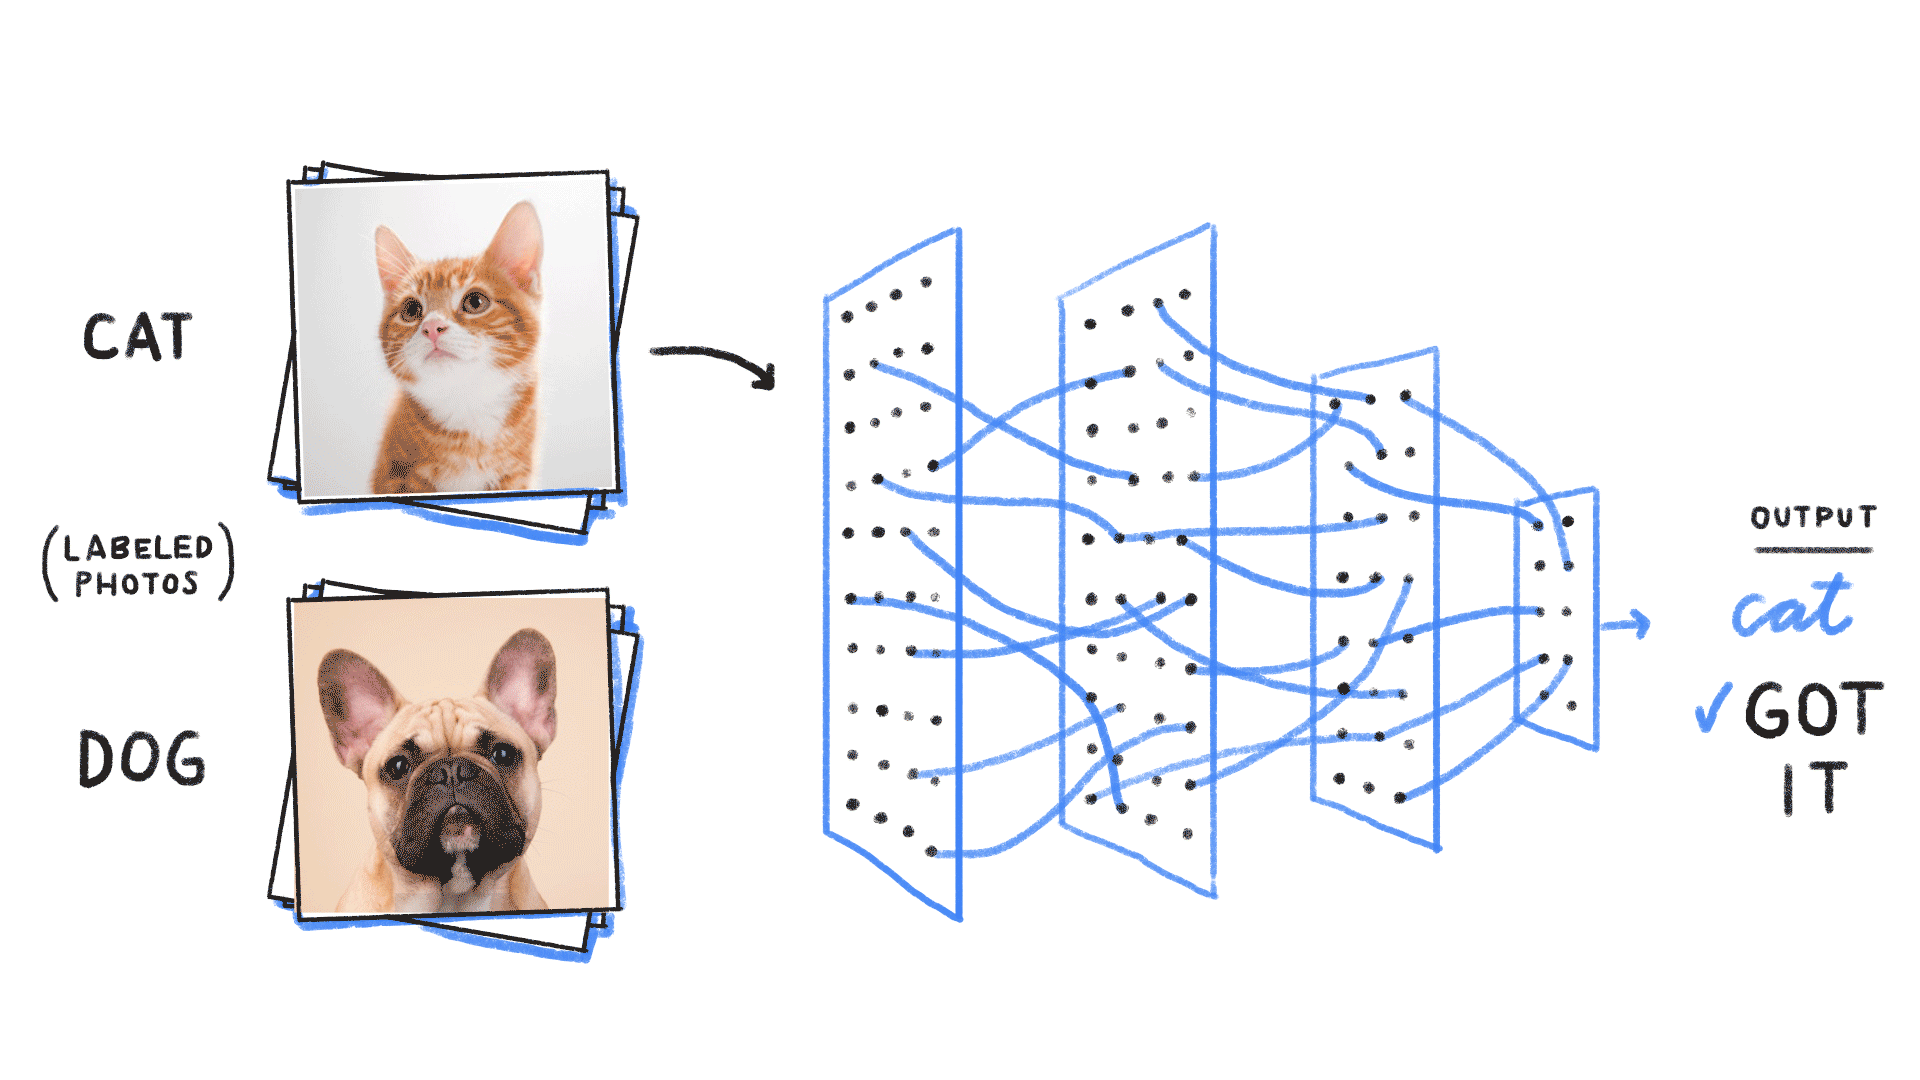
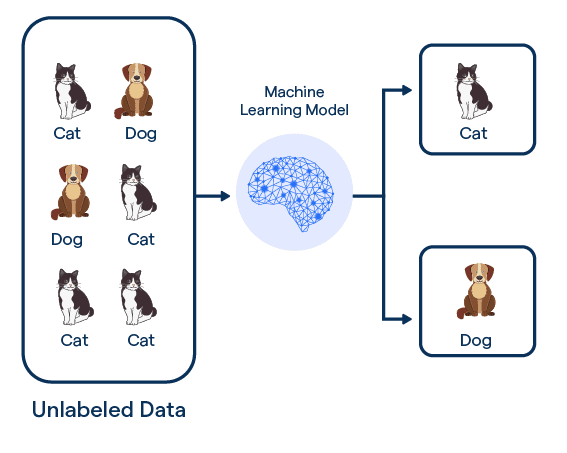
Supervised Learning
- Supervisor indica a resposta desejada para cada padrão de treinamento.
Unsupervised Learning
- Não existe supervisor indicando a resposta desejada.
Reinforcement Learning
- Aprender como agir
- Sem um professor
- Sem conhecimento prévio do ambiente
- Somente com base em recompensas (e punições)
- Reforços positivos
- Aumentam probabilidade de comportamento
- Reforços negativos
- Diminuem tal probabilidade
Agente
Ação
Próx. Estado
Recompensa
Ambiente
Reinforcement Learning
Agente
Ambiente
estado (s_t)
ação (a_t)
reward (r_t)
Política \textcolor{#00B050}{\pi : S \mapsto A}
\pi^* = \max\limits_{\pi} \sum\limits_t \gamma^t r_t
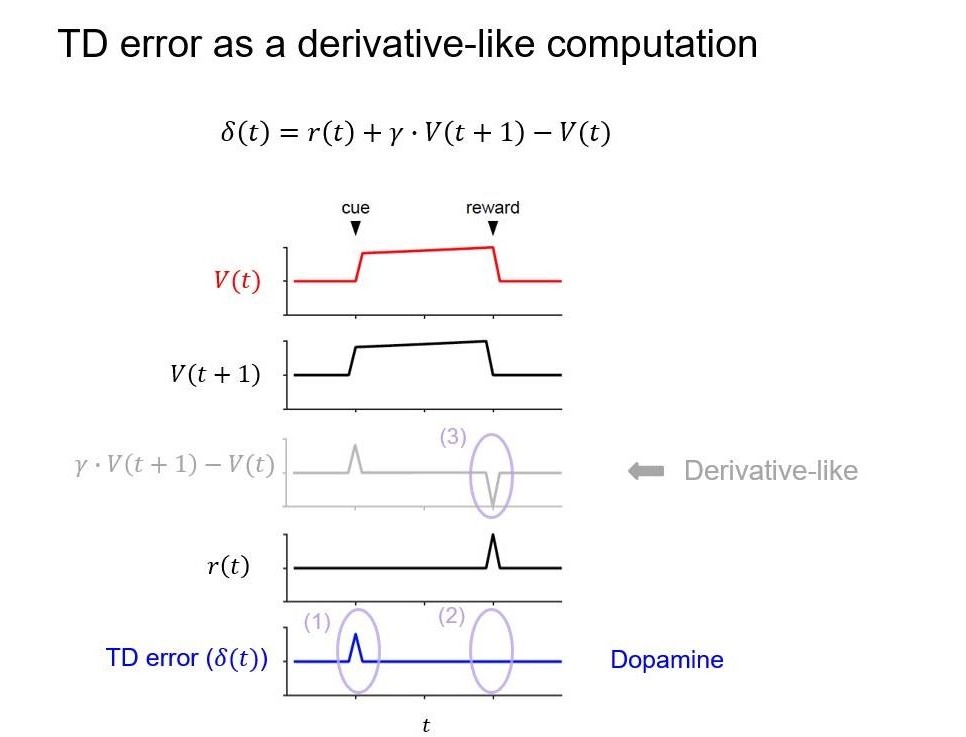
Temporal Difference (TD) Learning
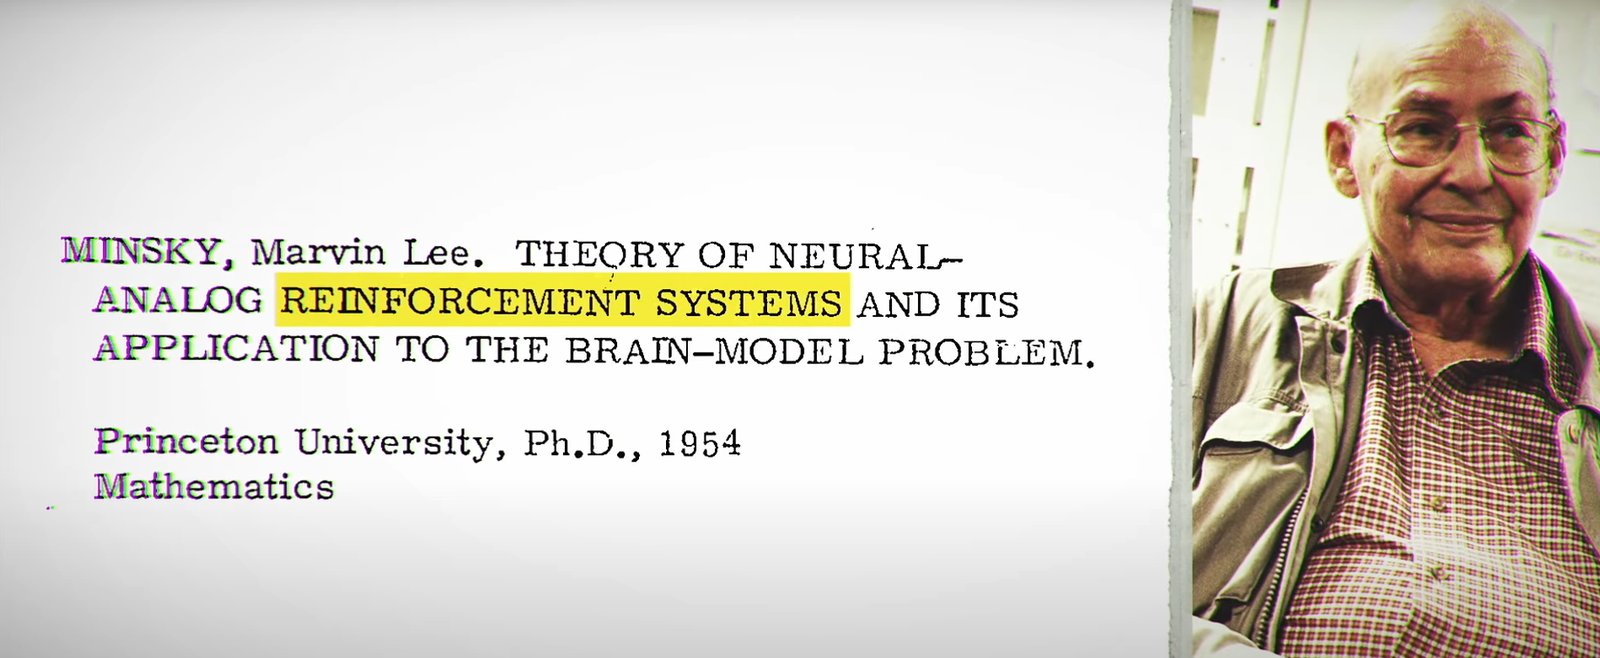
- Tese de Doutorado do Richard Sutton orientada pelo Andrew Barto
- Relacionado a Dynamic Programming
- Fortes relações com o sistema de dopamina do nosso cérebro
- Influência na área de neurociência
- A diferença entre a recompensa que o agente ganhou e o quanto de recompensa ele achava que iria ganhar
Atenção em RL
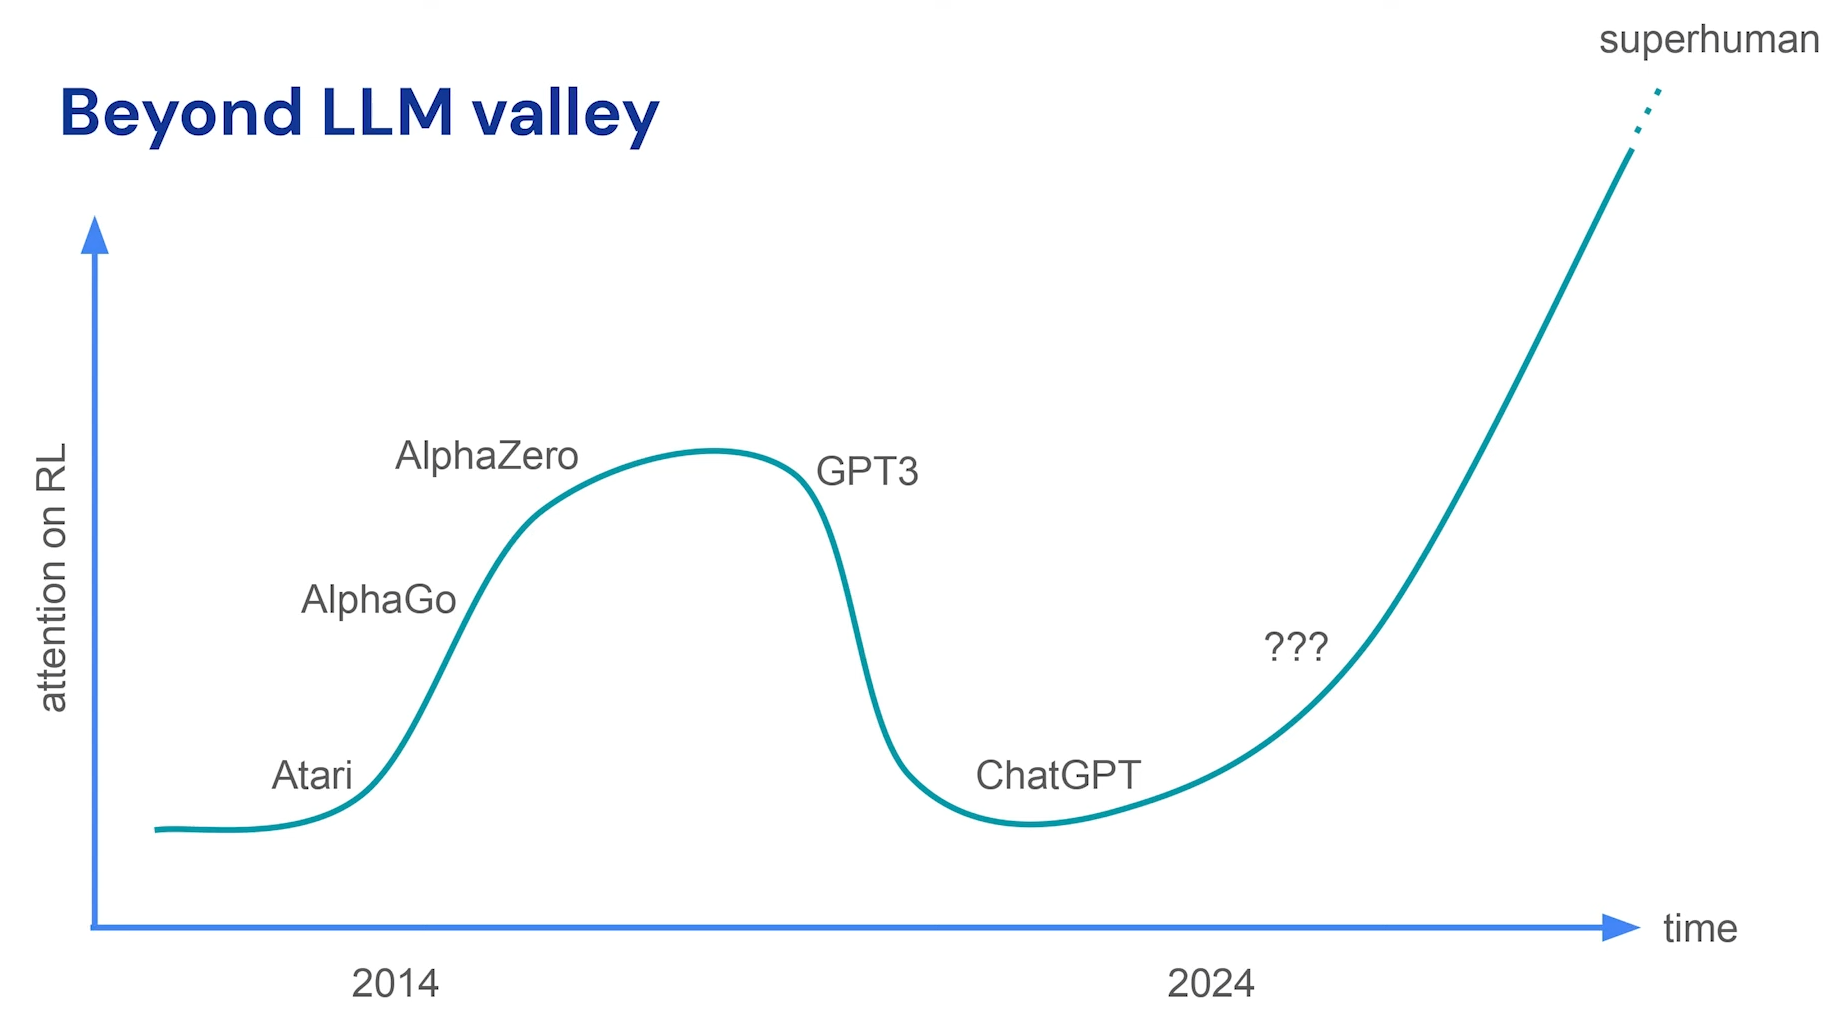
Atenção em RL
Atenção em RL
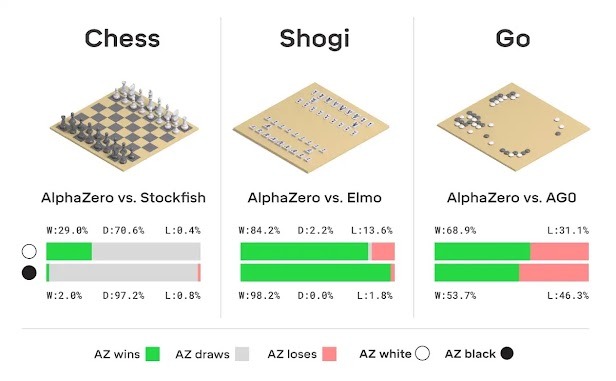
Alpha Zero
Atenção em RL
Atenção em RL
2020
Large Language Models (LLMs)
- Modelo de ML sofisticado que prevê qual palavra vem a seguir em qualquer trecho de texto.
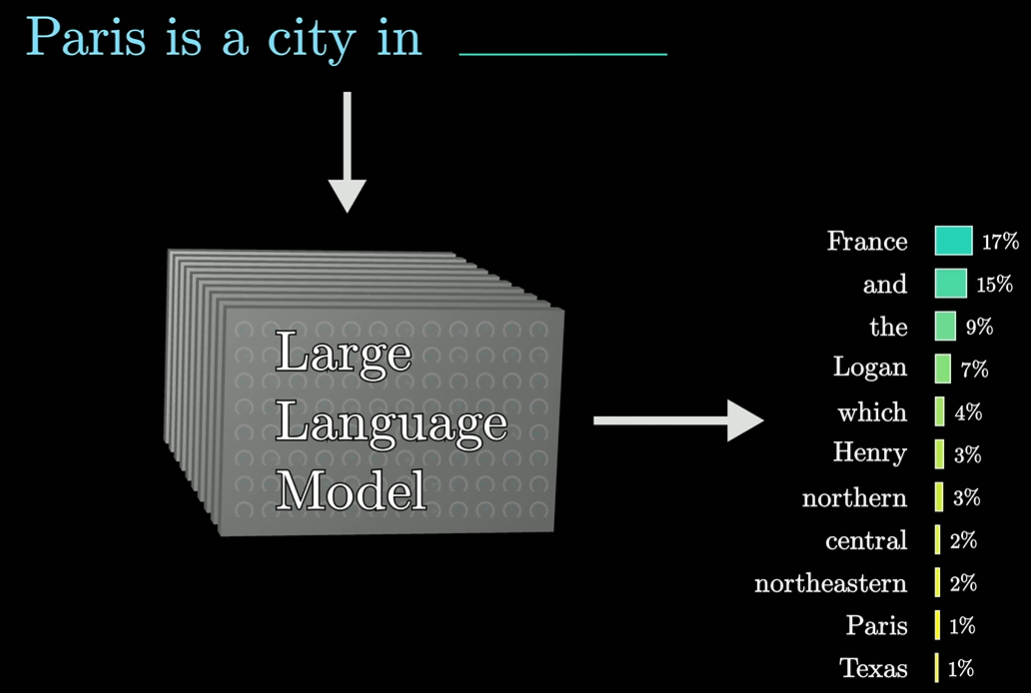
Large Language Models (LLMs)
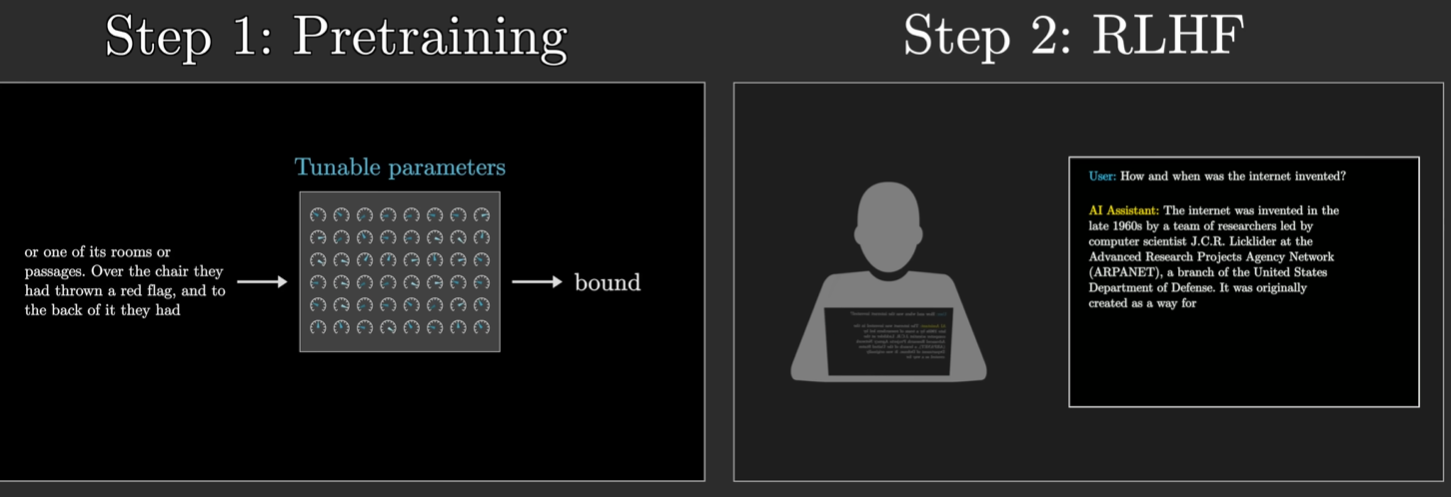
- RL sendo usado no pós-treinamento
- RLHF, Chain-of-Thought
Atenção em RL
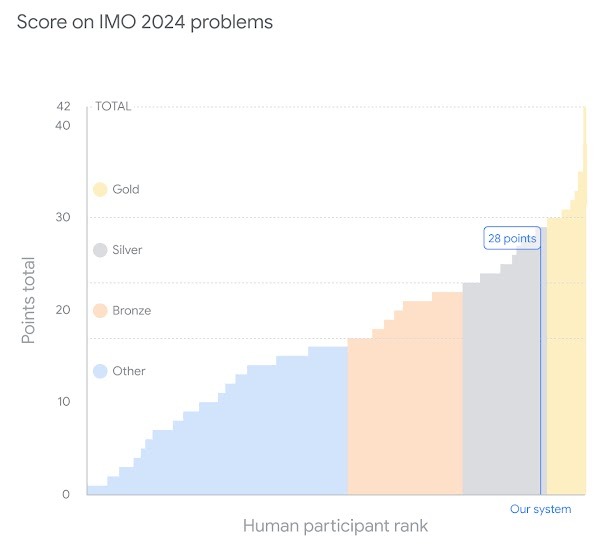
AlphaProof
AlphaProof
- AlphaProof, da DeepMind, combina LLMs com RL para provar teoremas matemáticos automaticamente no sistema Lean.
- Aprende de forma autônoma, gerando provas verificadas e melhorando com autoaprendizado contínuo.
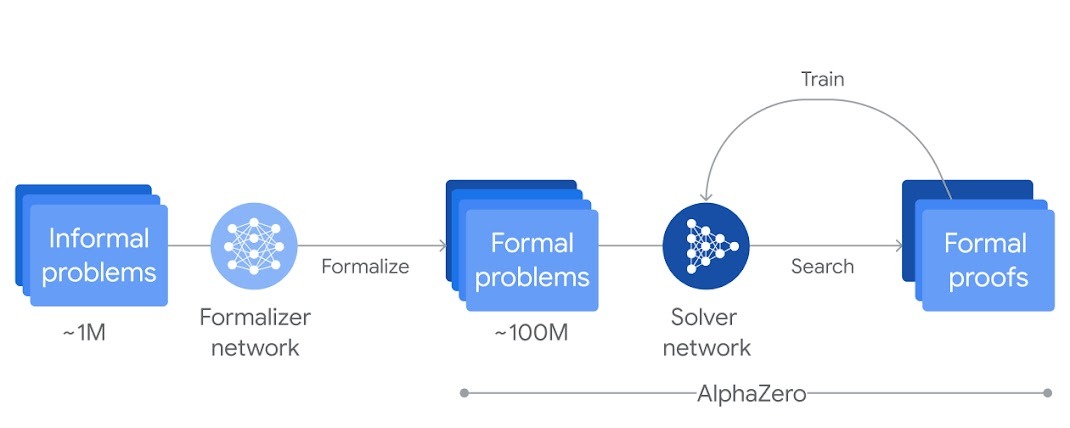
AlphaProof – IMO 2024
Atenção em RL
AlphaProof???
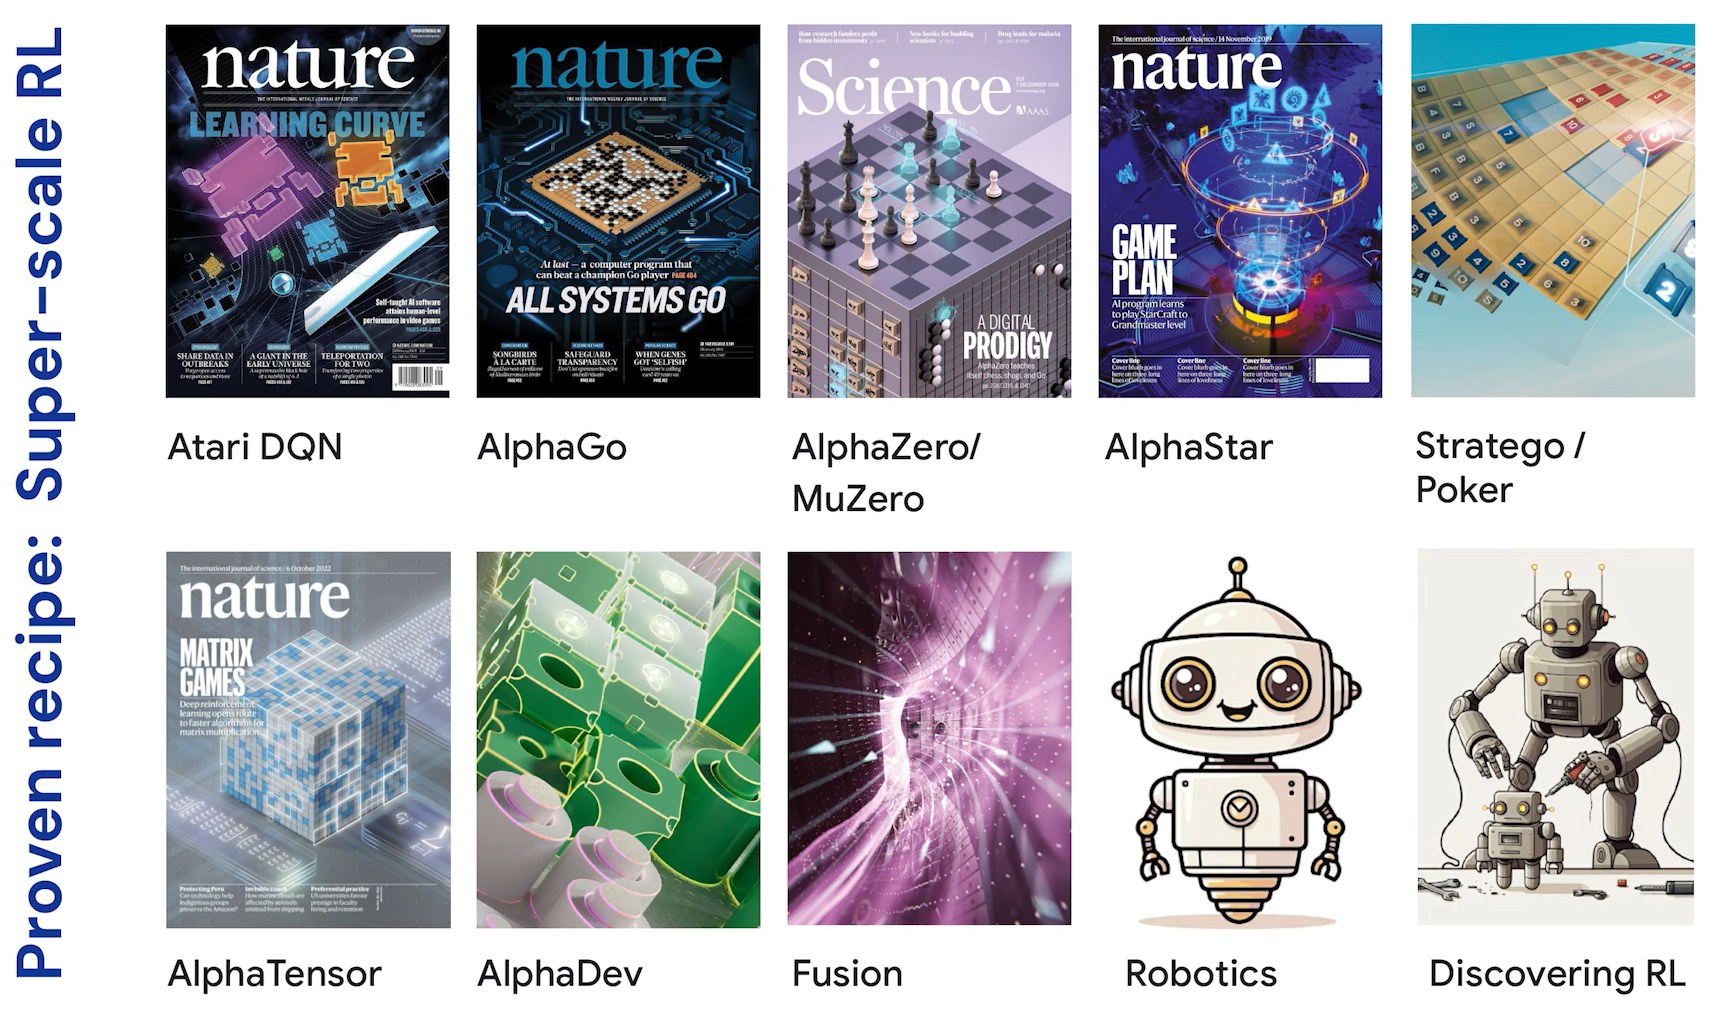
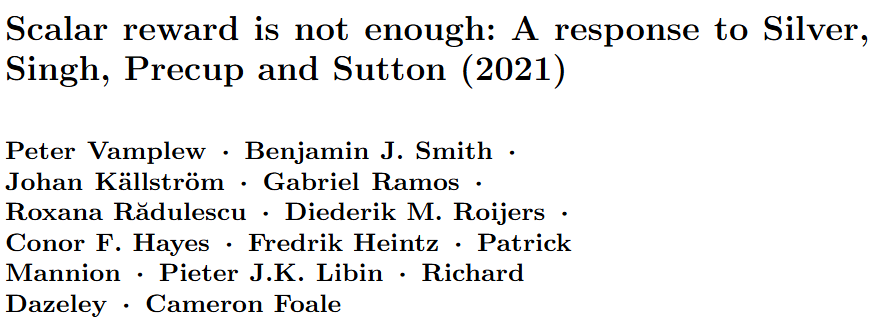
Receita: Super-Scale RL
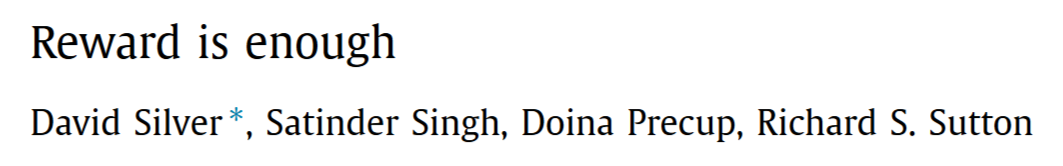
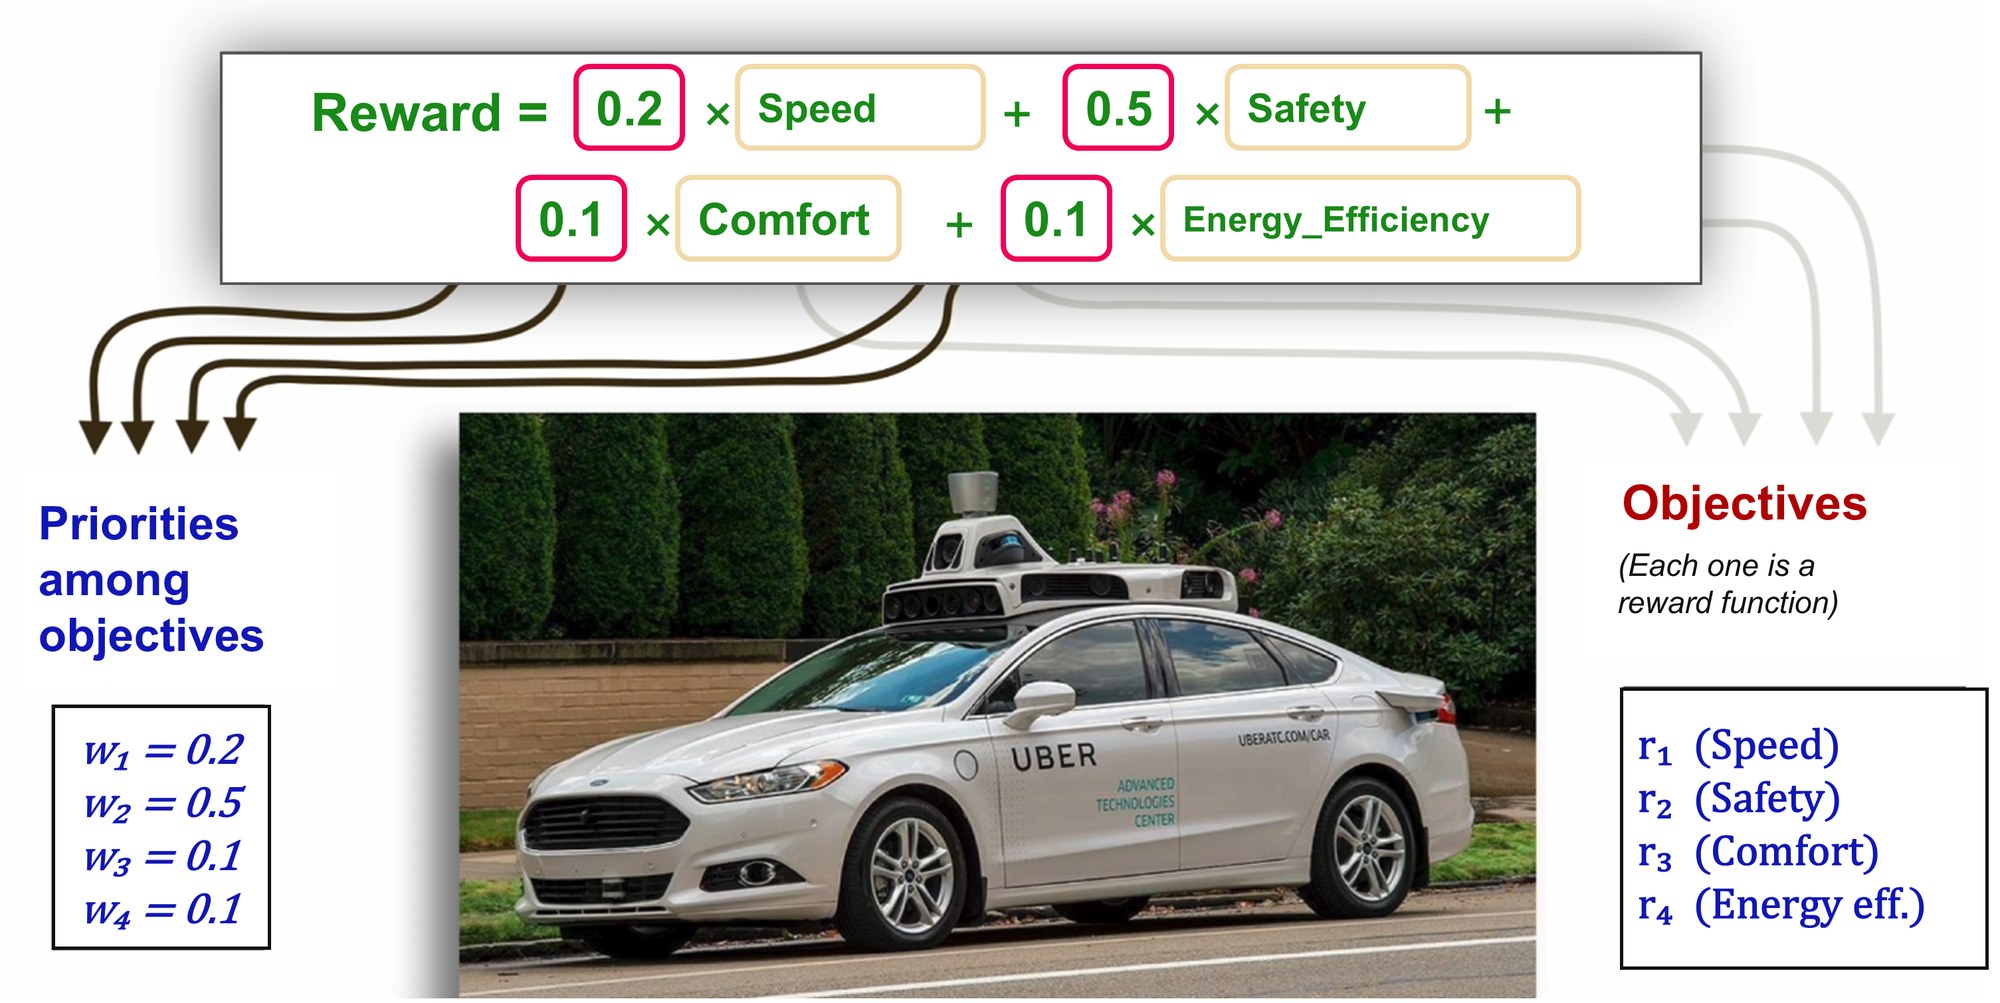
O mundo real é multiobjetivo
Sample Efficiency in MORL
- Many thousands of environment interactions are required to learn a set of policies! (one for each user preference)
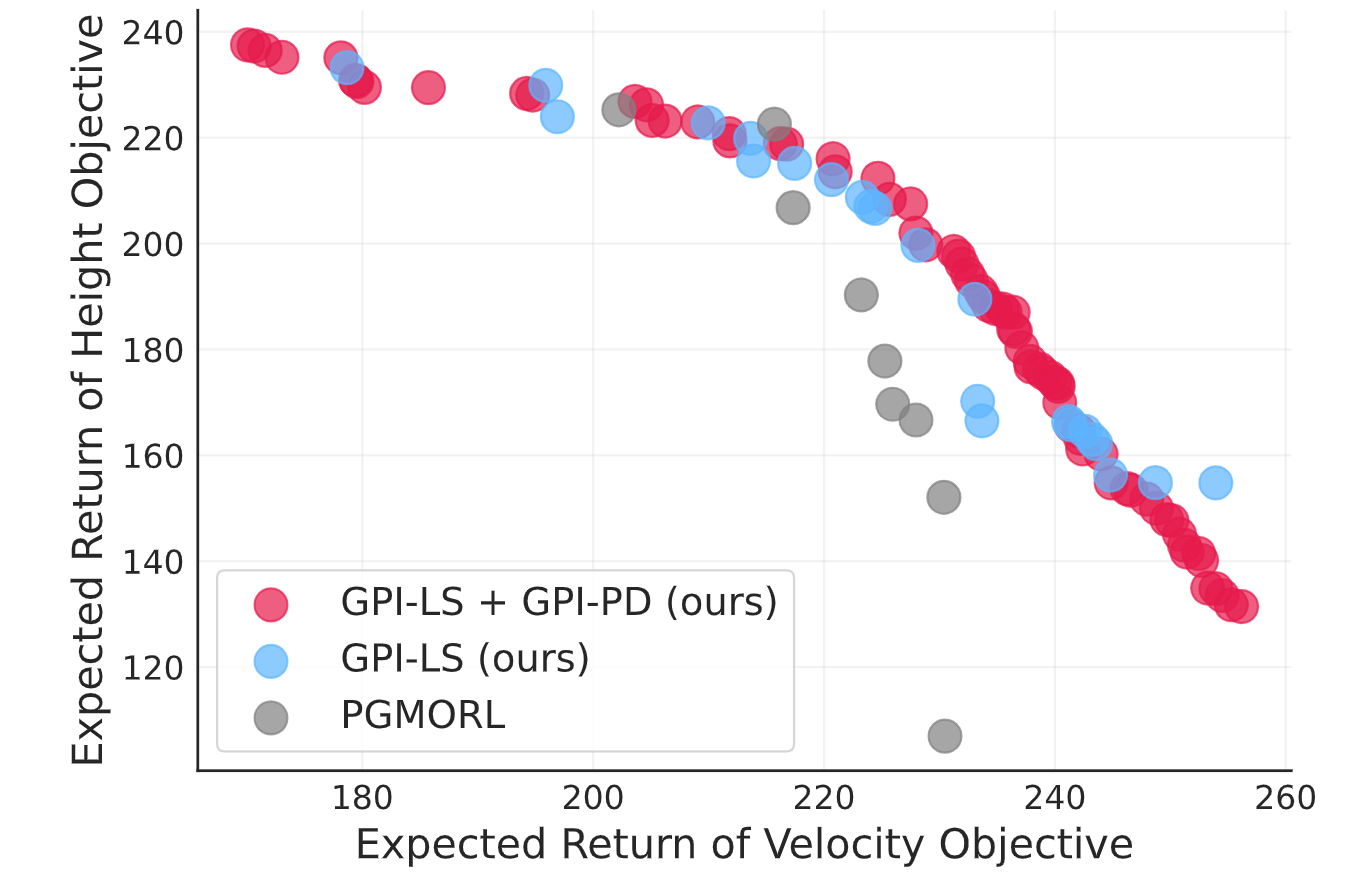
Infeasible in real-world settings!
e.g. autonomous driving, healthcare, robotics
How to learn a set of policies containing optimal policies for
any user preference in a sample-efficient manner?
MO Hopper – Pareto Front
Aprendizado por Reforço Multiobjetivo
- MO Super Mario Bros.
- 4 objetivos
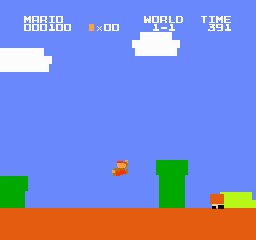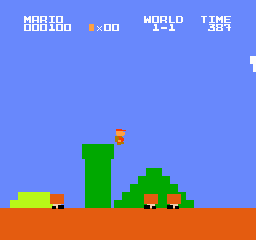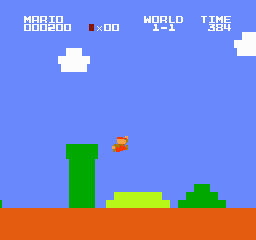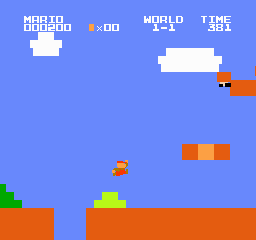
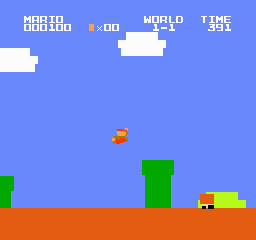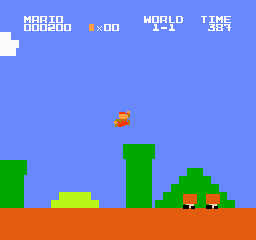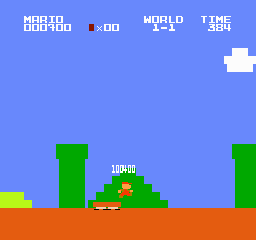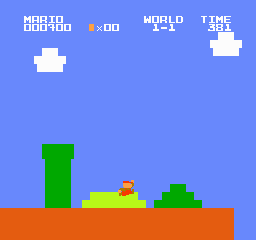
Time vs. Killing Enemies
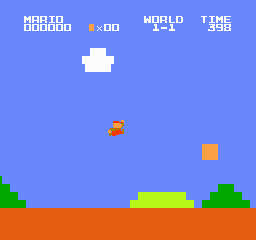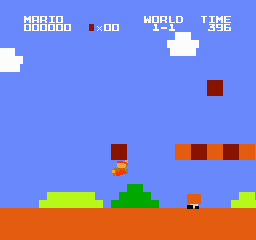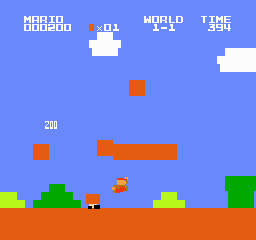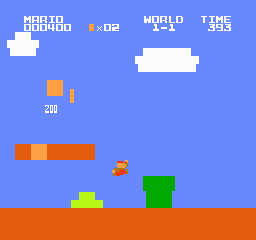
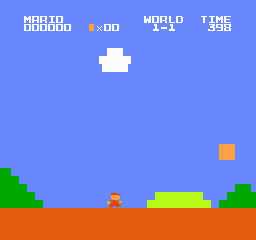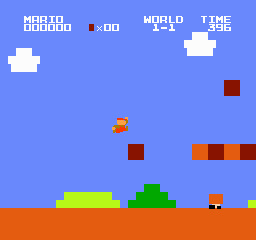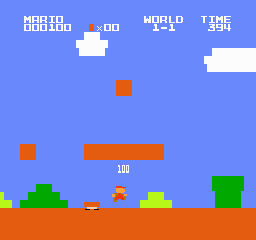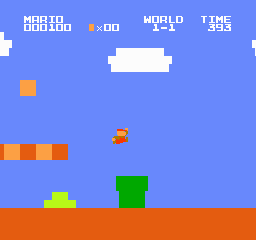
Coins vs. Time
Scaling GPI-LS to Image-Based Tasks
- MO Super Mario Bros.
- 4 objectives
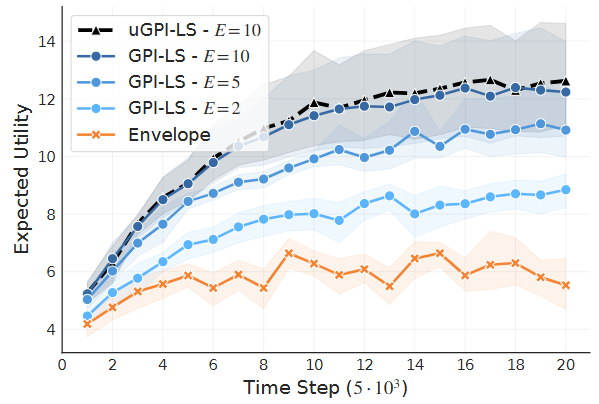
- GPI-LS performance improves as the ensemble size increases
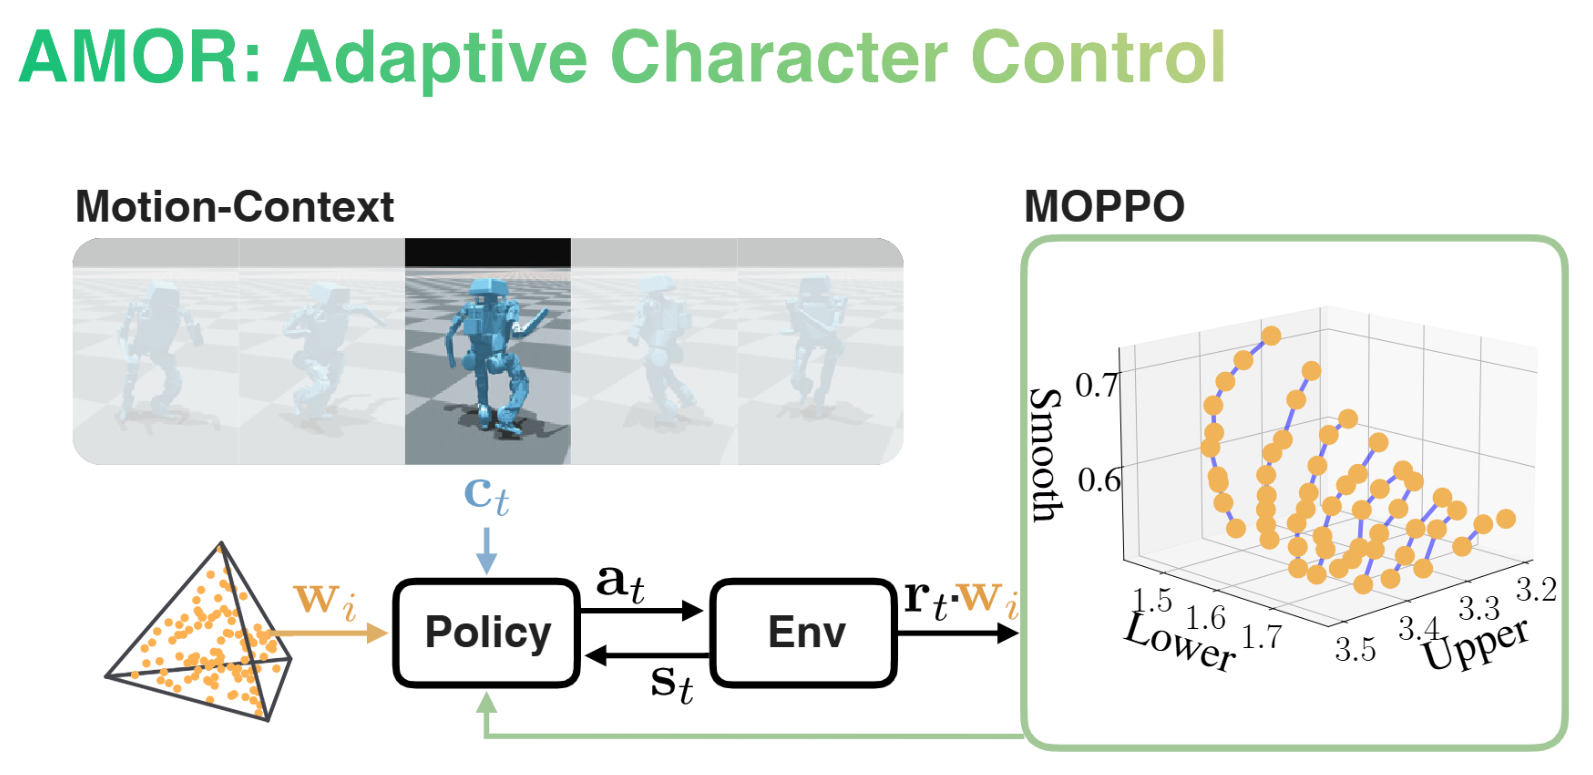
Disney Research
- Novo método que controla as preferências entre os objetivos on-the-fly
Além de Recompensas
- Model-Based RL
- Aprender um modelo do mundo
- Treinar o agente usando experiências geradas pelo modelo
- Abstrações Temporais
- Aprendizado hierárquico
- Ir até a porta vs. Mover a perna 2cm
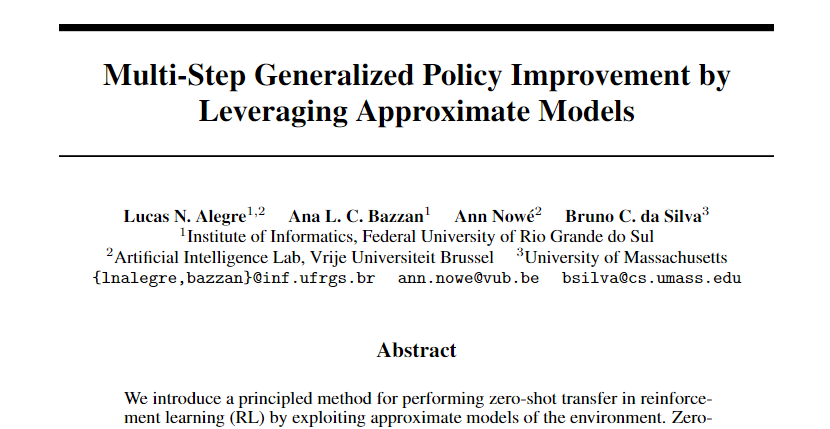
NeurIPS 2023
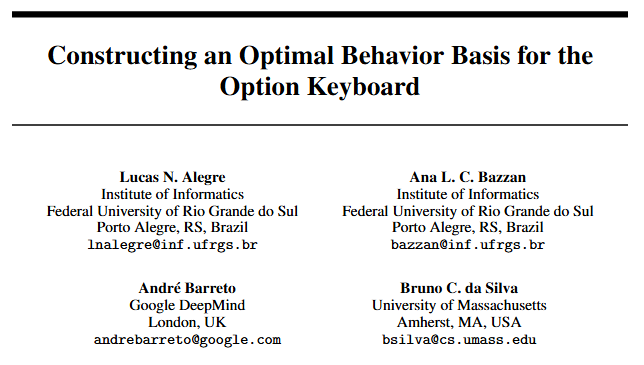
NeurIPS 2025
Como saber mais?
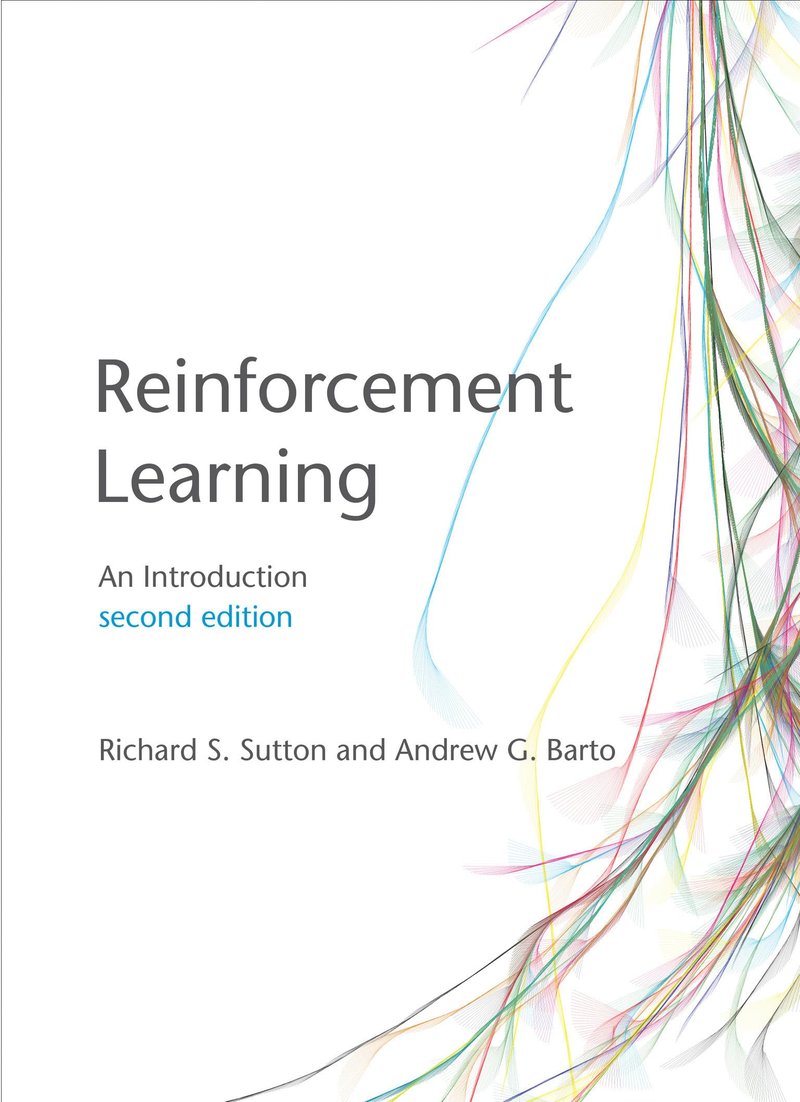
- “Reinforcement Learning: An Introduction” (Sutton & Barto)
![]()
- Disciplina de Aprendizado por Reforço do INF
- Prof. Anderson Tavares
- lnalegre@inf.ufrgs.br
- Sala 233 – Prédio 43424
![]()
Reinforcement Learning e
a Era da Experiência
Muito Obrigado!